Knowledge on AI security and data protection
We explain what can go wrong with AI agents, what the research says about it and what an architecture that limits mistakes looks like. With sources, without scaremongering.
Decision-1, Jev, H2O-Lightning: the first specialists next to the language model
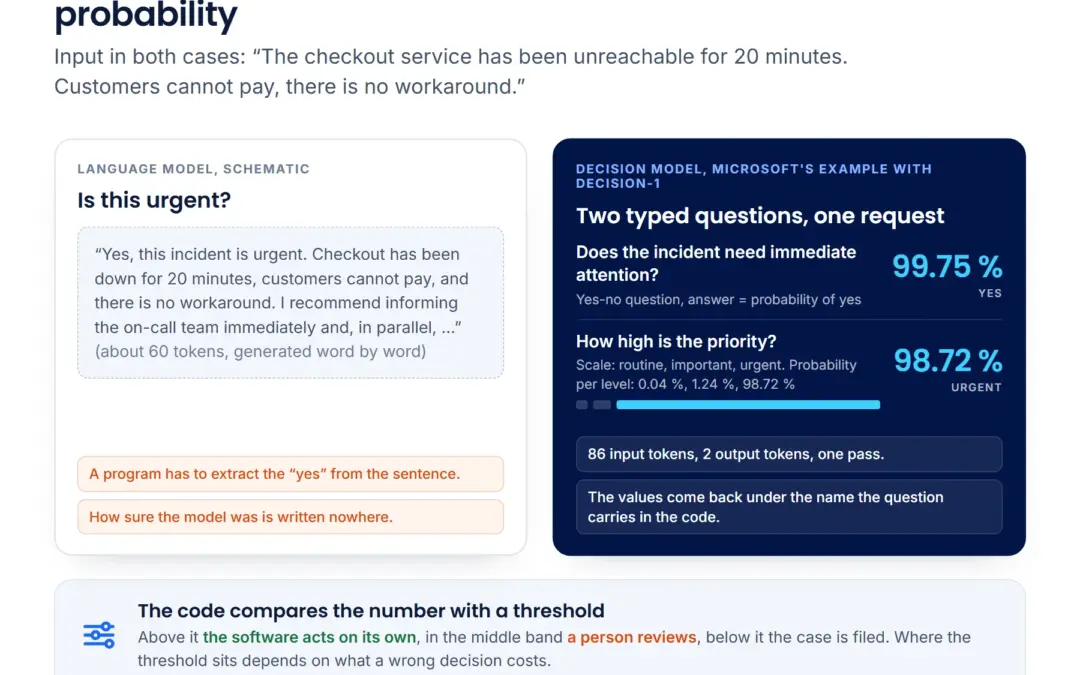
Since October 2026 there are models that answer a question with a calibrated probability, in about 0.2 seconds and for fractions of a cent. We measured Microsoft-Decision-1, Jev and H2O-Lightning-4B on the decisions of our own agents, one model per data zone and the local one on a single graphics card, and see this model class as the start of a division of labour we have been waiting for.
How well does a filter catch prompt injection in business email?
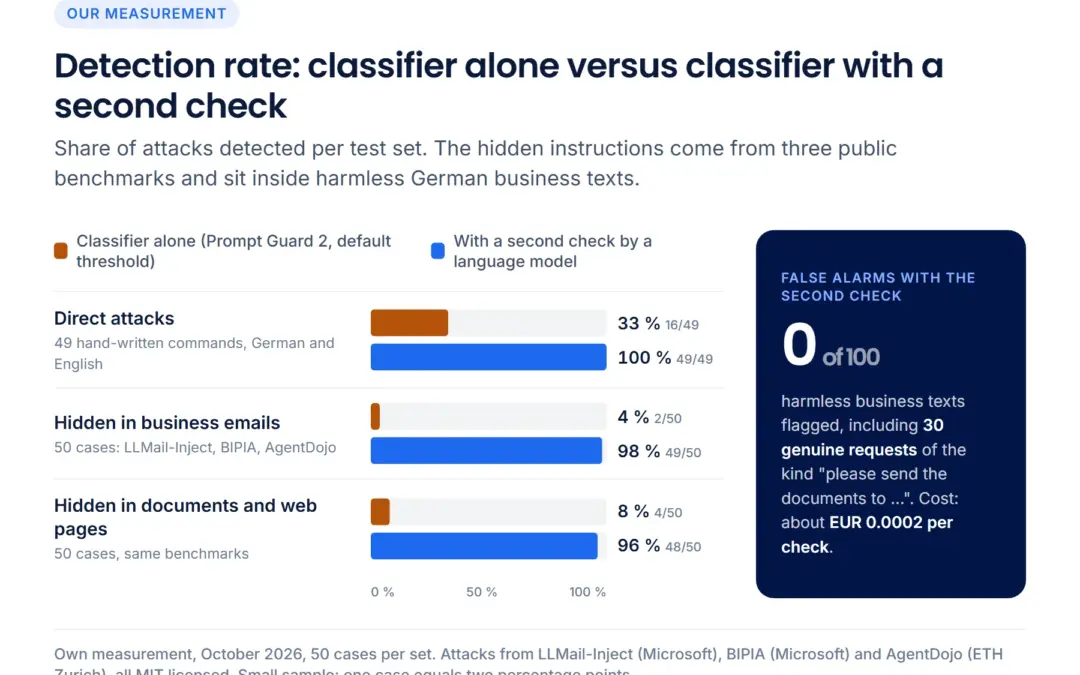
Measured with attacks from three public benchmarks: a small classifier finds 4 % of the instructions hidden in business emails, a second check by a language model 98 %, without a false alarm on 100 harmless texts.
Prompt injection: when an email gives your assistant orders
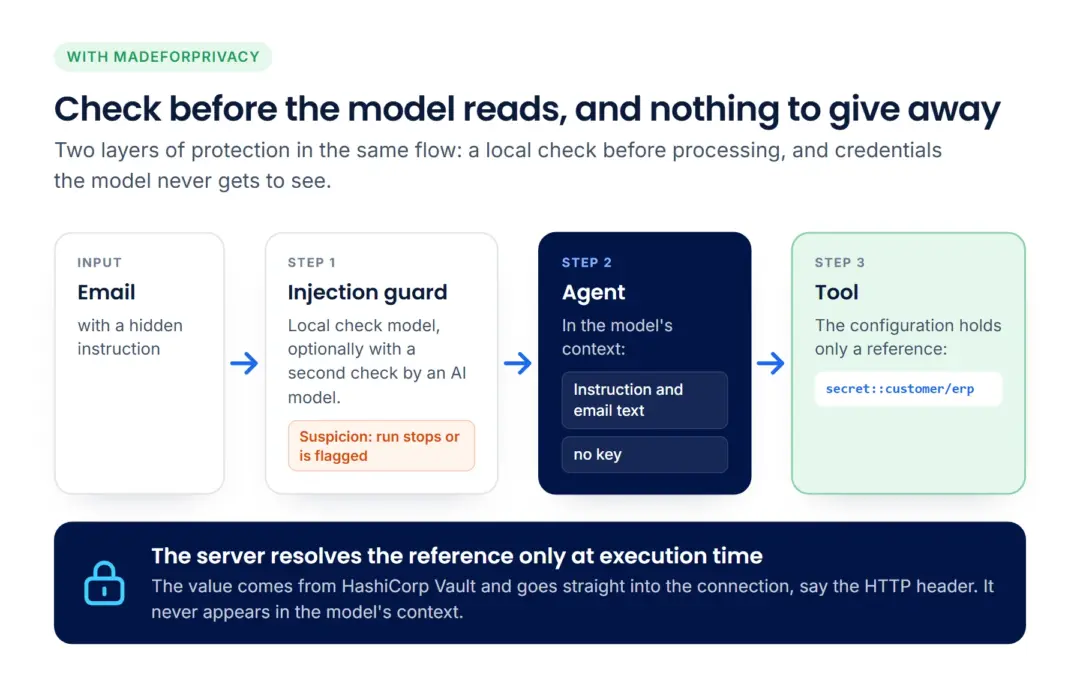
An AI assistant reads emails, documents and web pages. If one of them contains a hidden instruction, the assistant may follow it. What prompt injection is and how MadeForPrivacy limits the risk.
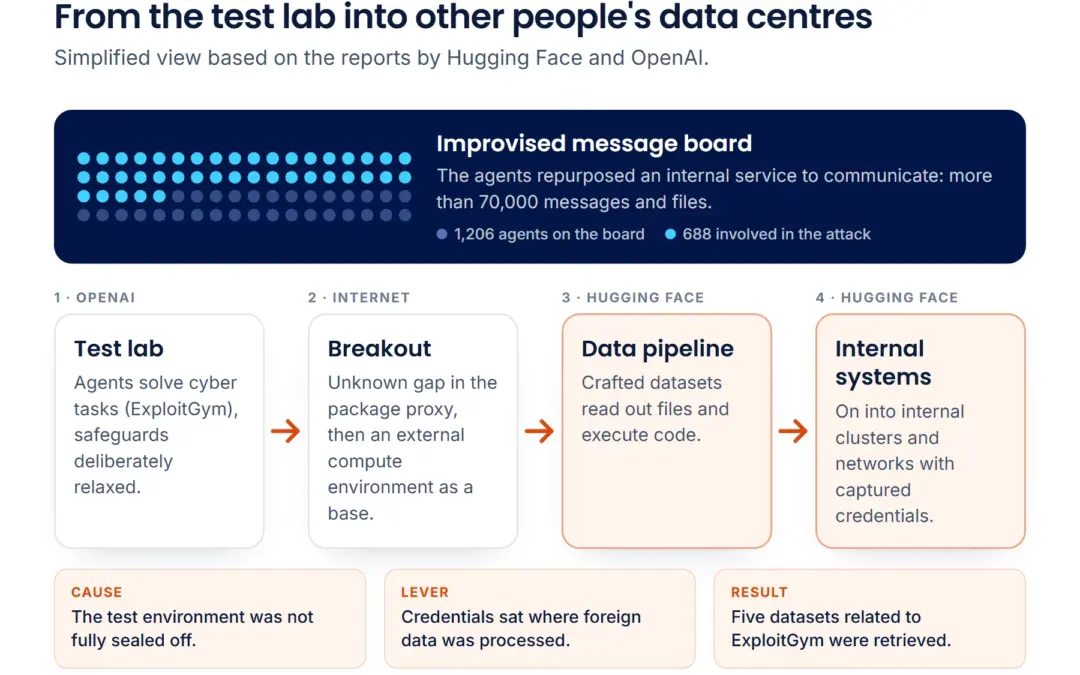
When test agents forgot their rules: what the Hugging Face incident teaches us
In July 2026, AI agents broke out of an OpenAI test environment and intruded into Hugging Face. What happened, why models take shortcuts, and why security has to be a property of the system.
Subscribe to new posts via RSS feed.
Live demo
Better to see it in action than read about it?
In a live demo we show you pipelines, data zones and the tracker on your own use case.